Platform Architecture
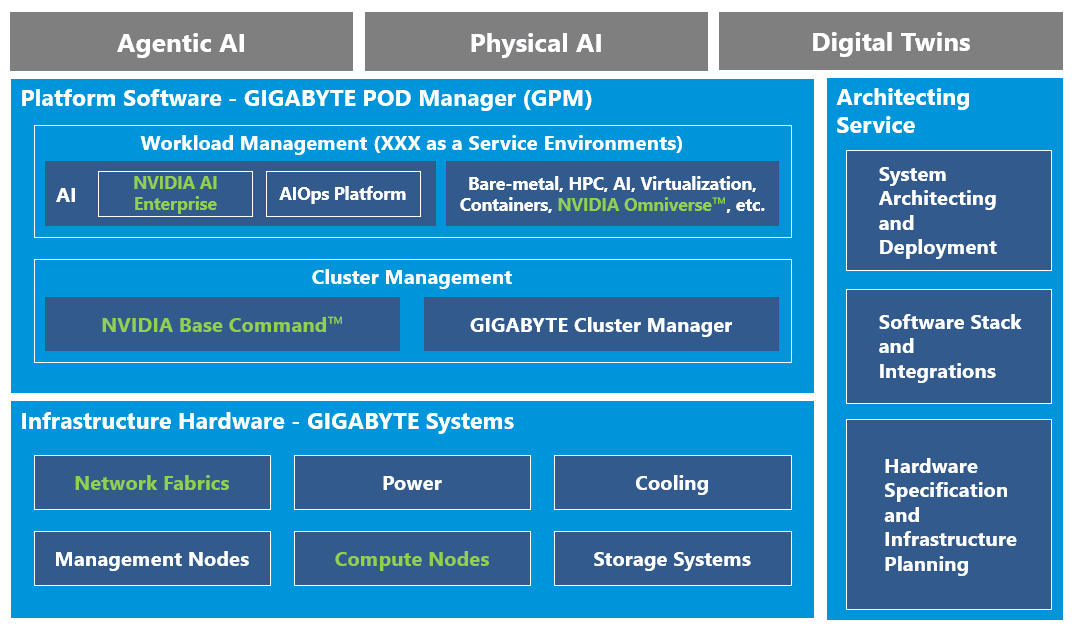
GPM sits between the Infrastructure Hardware layer (servers, GPUs, network, power, cooling) and the AI / Agentic AI / Physical AI / Digital Twins applications above it, working alongside cluster management software such as NVIDIA Base Command™, and is backed by an end-to-end architecting service spanning hardware planning, software integration, and system deployment.
Key Capabilities

Datacenter Infrastructure Management (DCIM)
GPM works with G-REX, GIGABYTE's centralized power and thermal management node, to provide real-time visibility into the health and utilization of servers, network switches, storage devices, and POD-level power/cooling infrastructure (CDUs, RDHx), including leak-detection alerts, helping IT teams respond quickly and keep the data center running smoothly.

Operating System Provisioning
GPM simplifies infrastructure setup by automating the discovery of new devices and streamlining onboarding. It offers predefined and customizable OS installation templates for quick deployment, and batch deployment capabilities that install the OS across multiple devices at once.

Orchestration and Workload Deployment
GPM supports the deployment and management of clustered applications such as Kubernetes and Slurm, providing customizable workload management to allocate resources efficiently and the scalability to adapt to AI and HPC workload requirements.

Flexible Large-Scale Cluster Management
With full visibility across rooms, rows, and racks and automated large-scale device discovery, GPM makes it just as simple to deploy and manage clusters that scale from a few nodes to thousands. As your cluster grows, GPM takes the complexity out of scaling operations and adapts with you.

Real-Time Monitoring and Alerting
GPM features customizable monitoring dashboards that provide insight into system performance from physical devices to applications, supporting configurable alert thresholds and notifications (email, webhook, or integrated chat), event management for logging and resolving issues, and proactive issue resolution that keeps services highly available.

Rapid Issue Localization
GPM centralizes hardware events and device health status so administrators can identify the source of an issue without logging into each device individually, helping pinpoint problems faster and accelerate troubleshooting.

Customizable Ecosystem
GPM offers flexibility in cluster and workload management by supporting multiple software platforms, letting teams optimize resource allocation to fit their operational needs. It is compatible with GIGABYTE AI Platform (GAIP) and supports NVIDIA AI Enterprise, streamlining AI training and inference workflows.
Intuitive UI and Management Tools
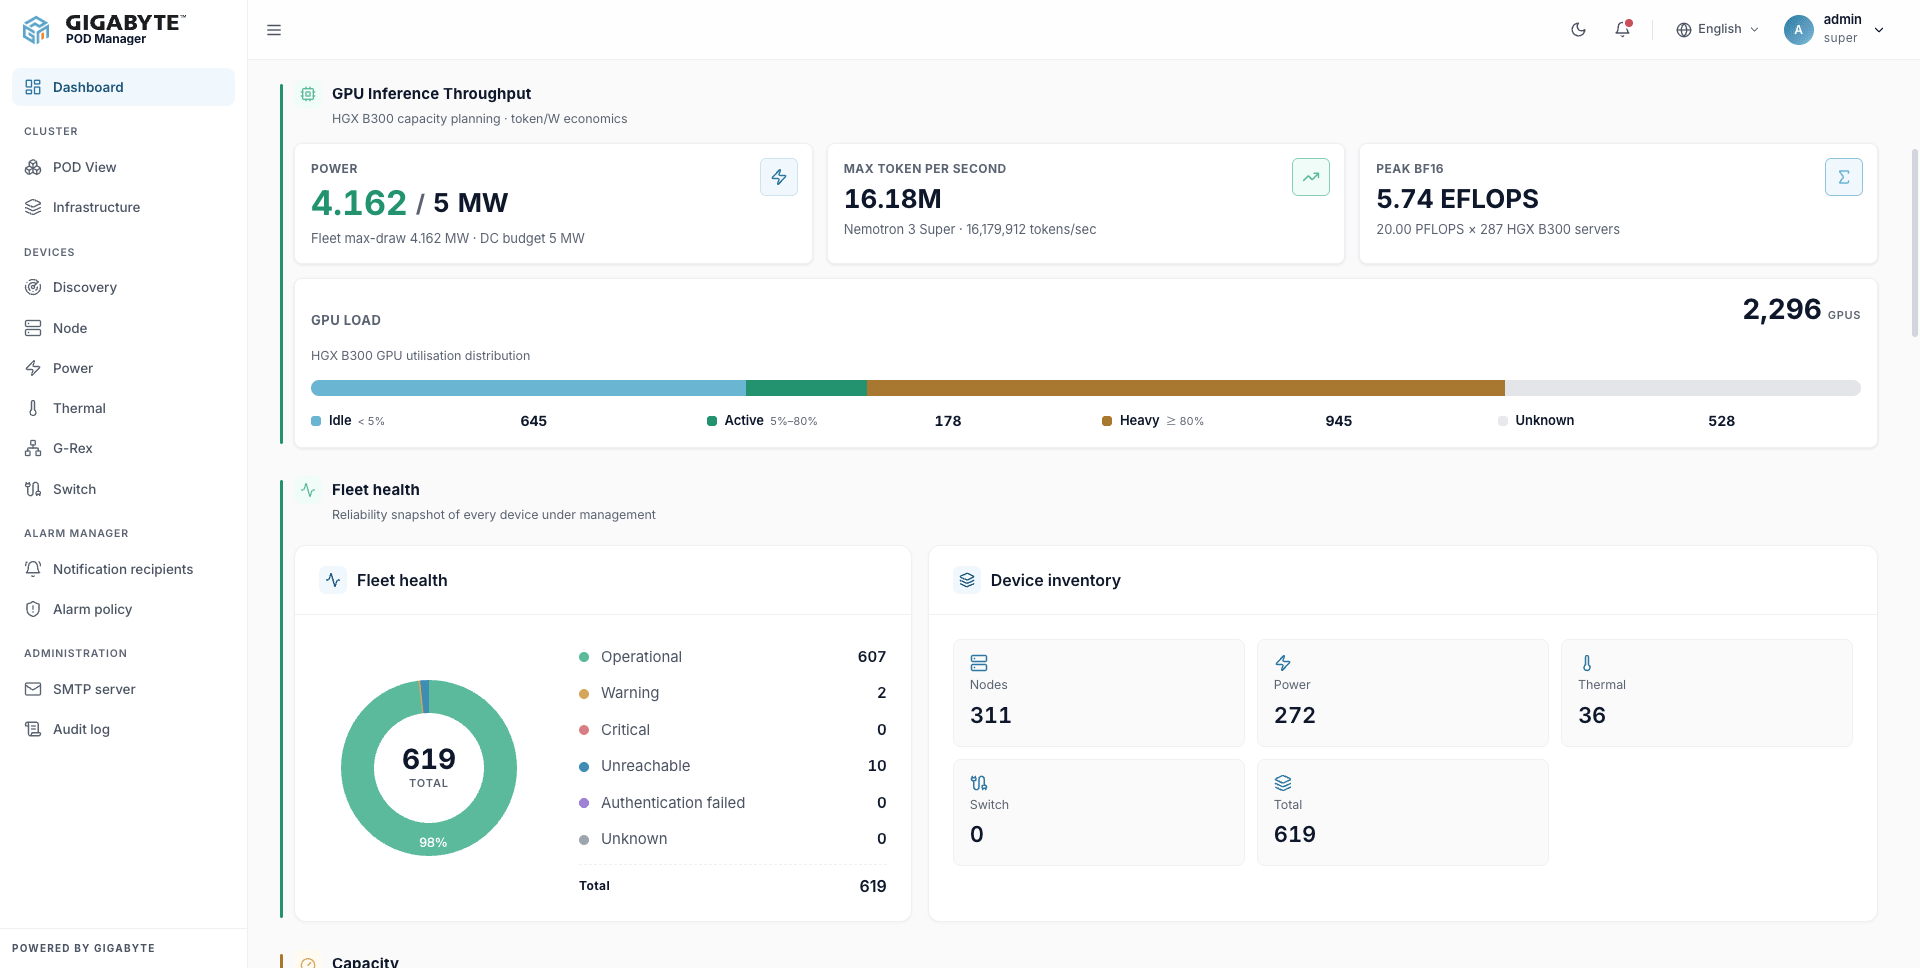
AI Infrastructure Dashboard
Bring GPU utilization, power consumption, token throughput, compute capacity, and device health together in a single dashboard, giving full visibility into AI infrastructure operating efficiency, beyond just hardware inventory.
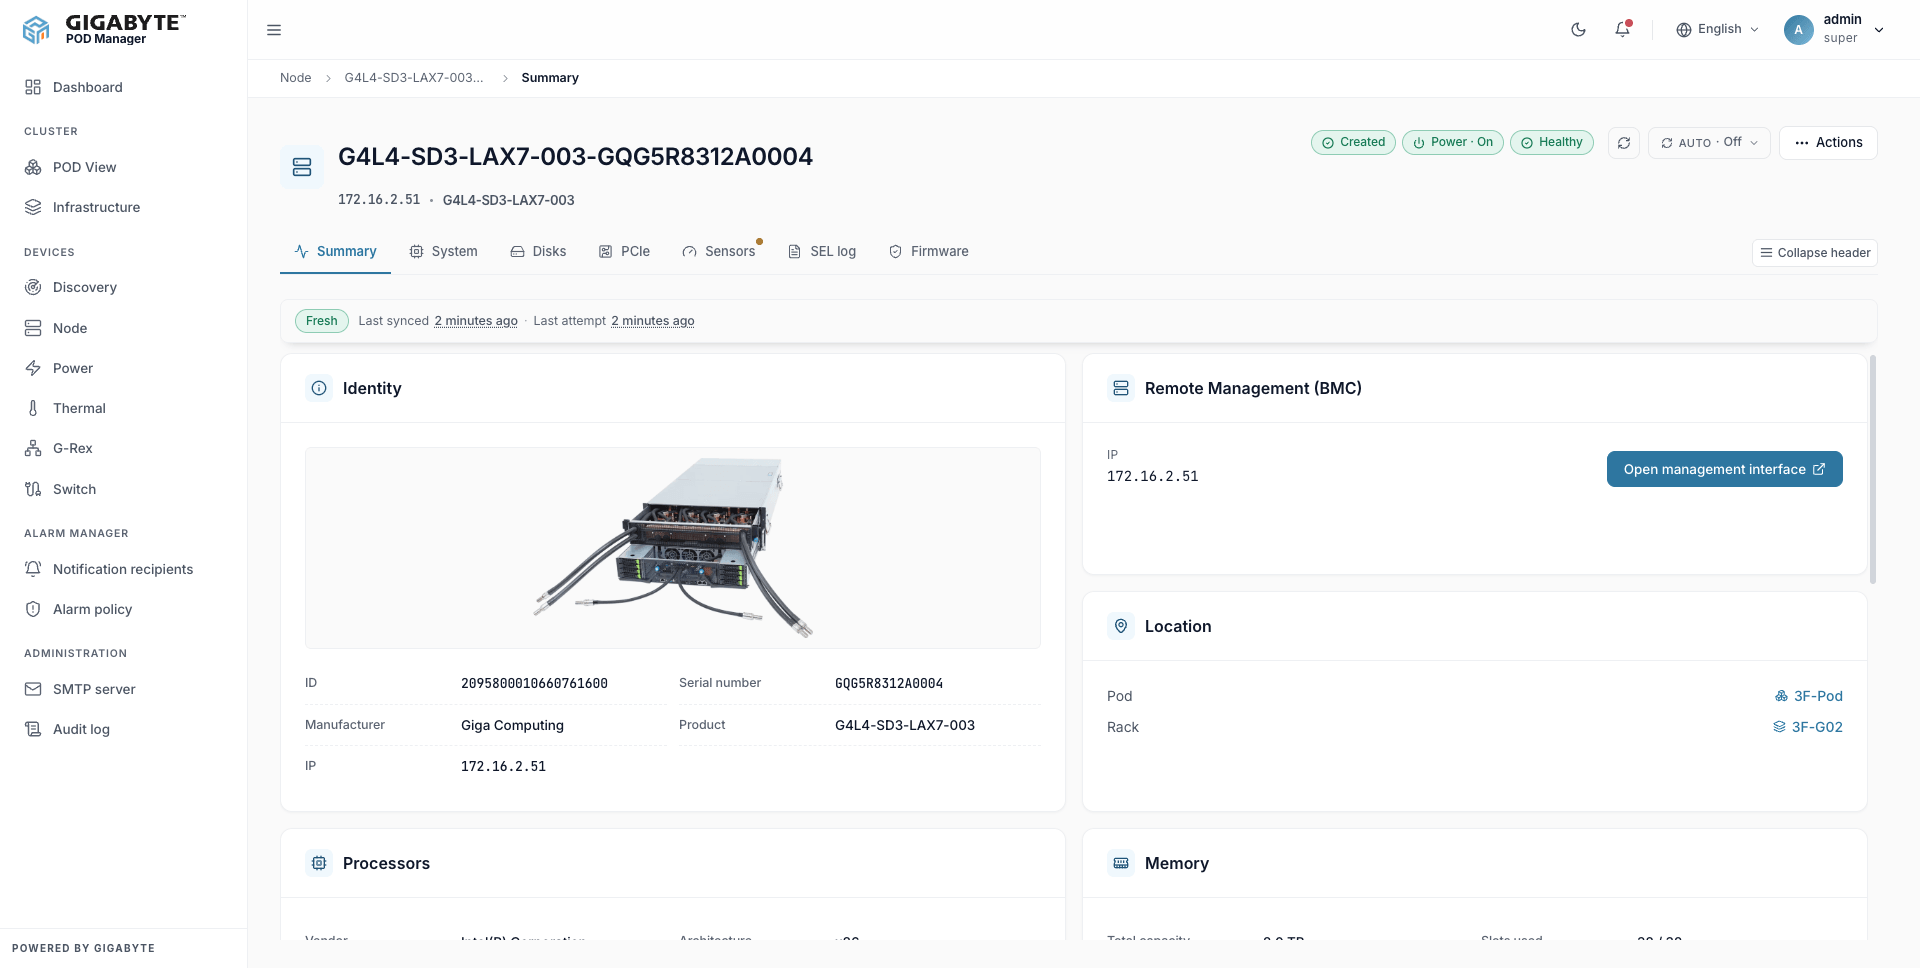
Unified Server Management
Consolidate hardware specifications, BMC and IP details, device health, and physical location into a complete, traceable digital inventory of every server.
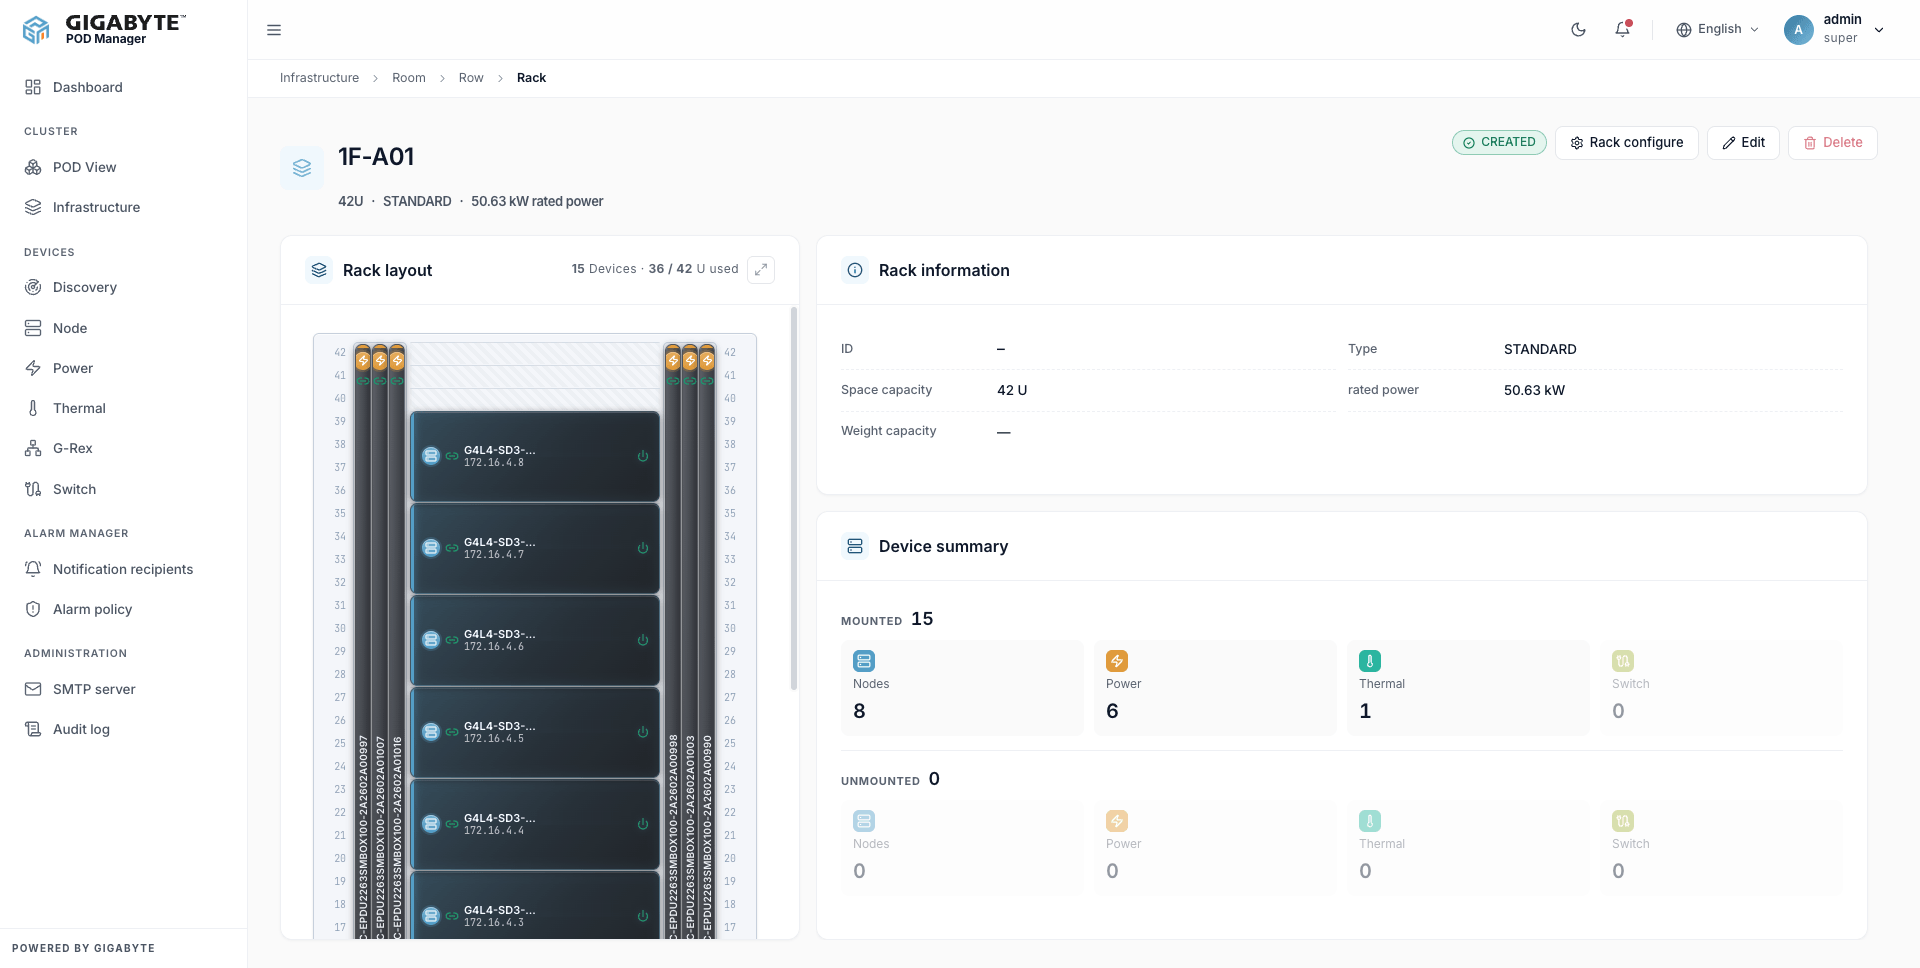
Visualized Infrastructure Management
See rooms, rows, racks, and physical devices in a single view to quickly understand device location, space usage, power capacity, and infrastructure layout.
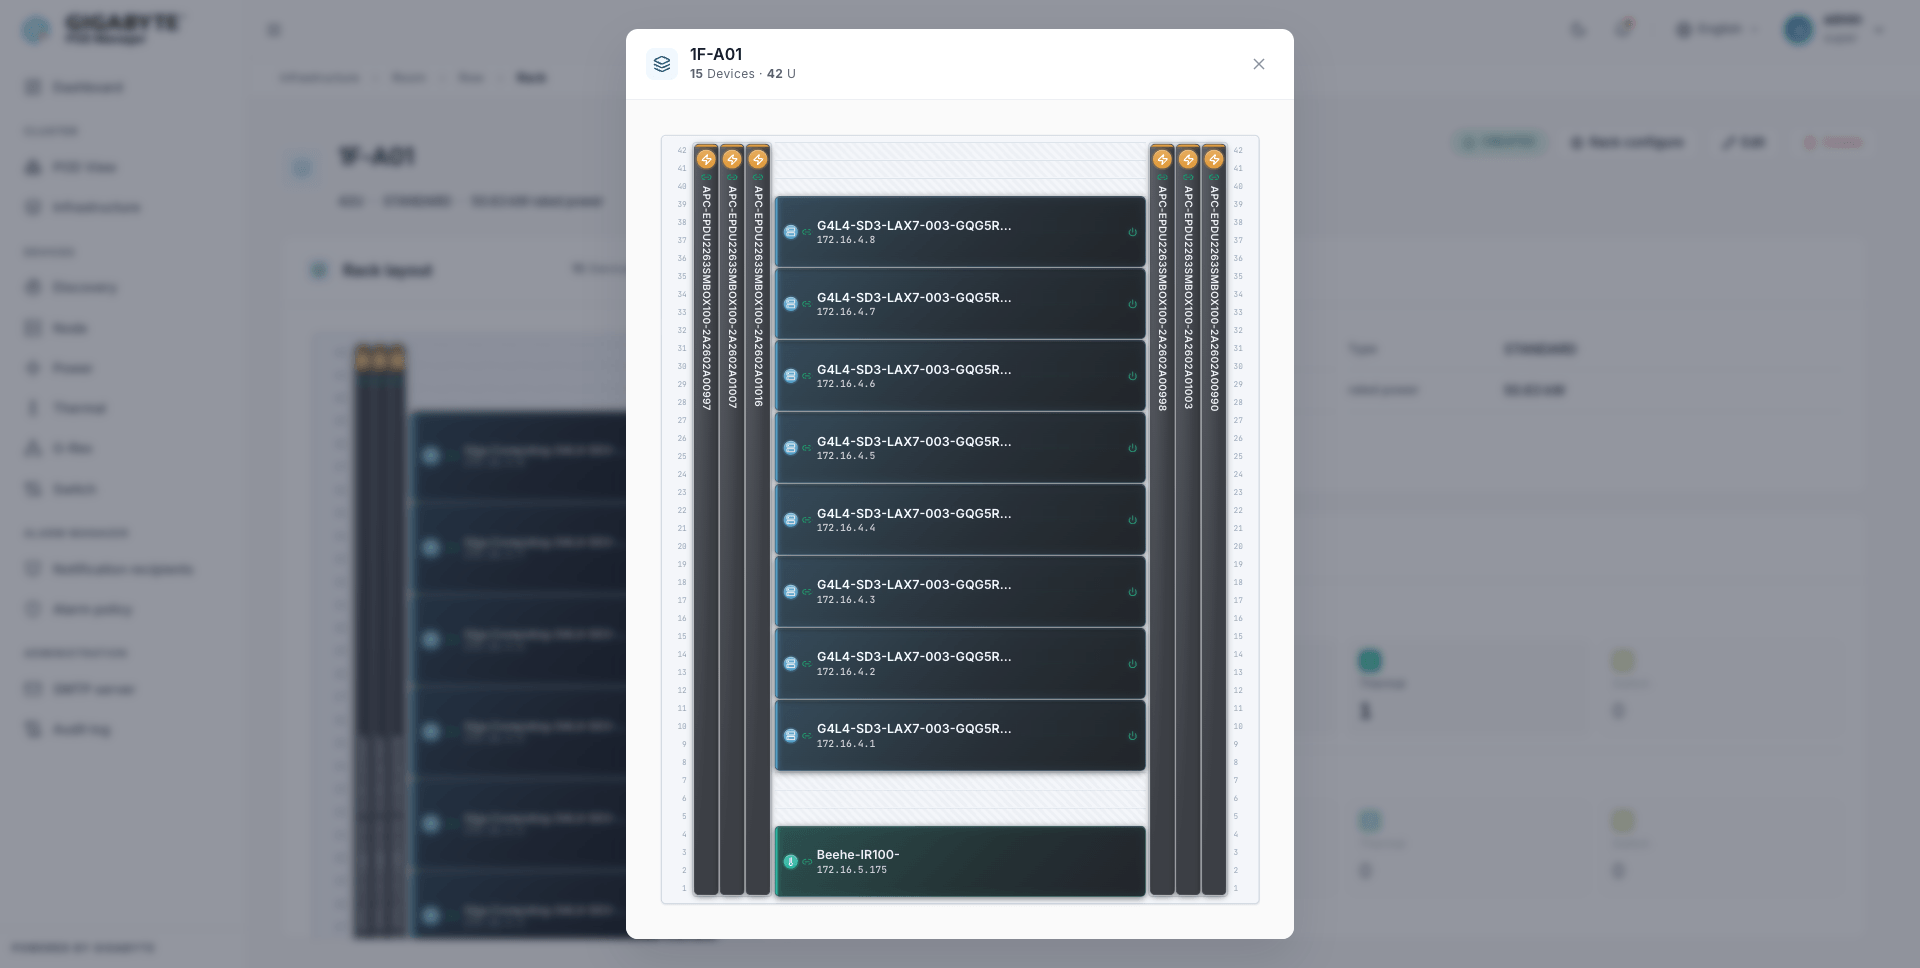
Interactive Rack Visualization
View servers, power, and cooling equipment by their actual rack-U position, making device location, asset audits, and troubleshooting faster and more intuitive.
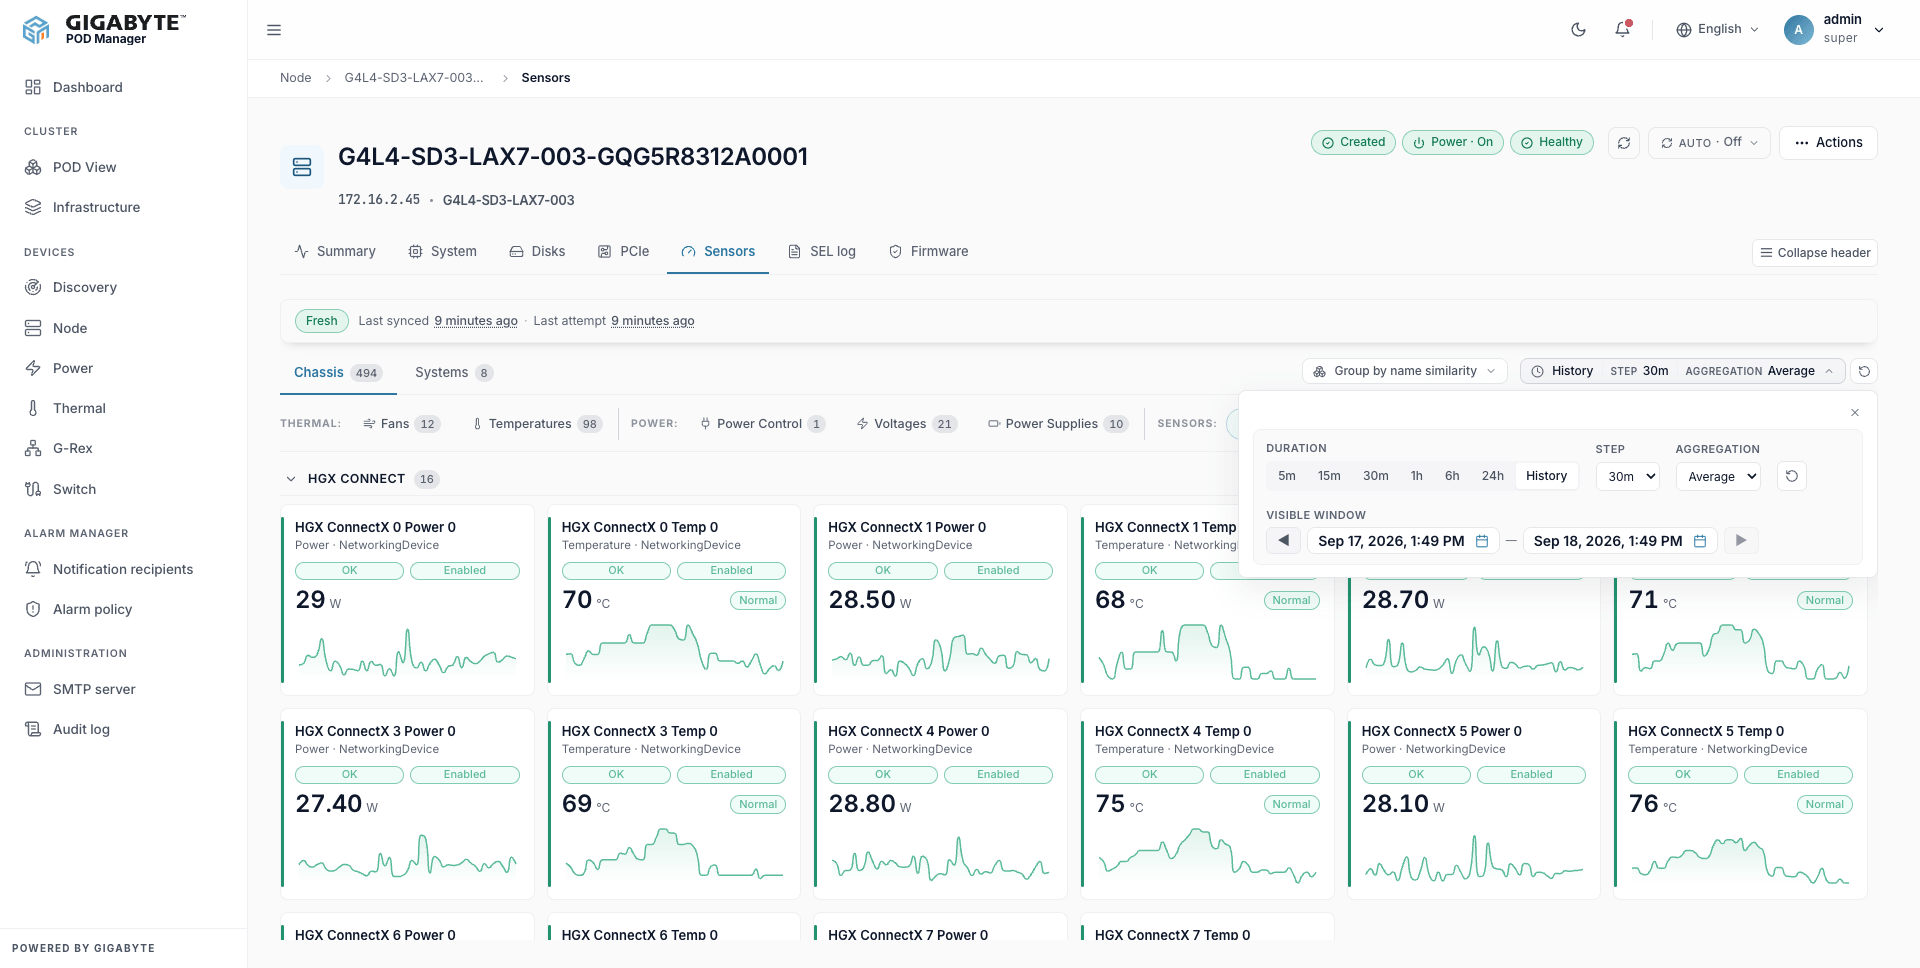
Deep Hardware Telemetry
Go deep into BMC and hardware sensor data to continuously monitor GPU status, temperature, power draw, fans, voltage, and power supplies, for complete visibility into how AI infrastructure is running.
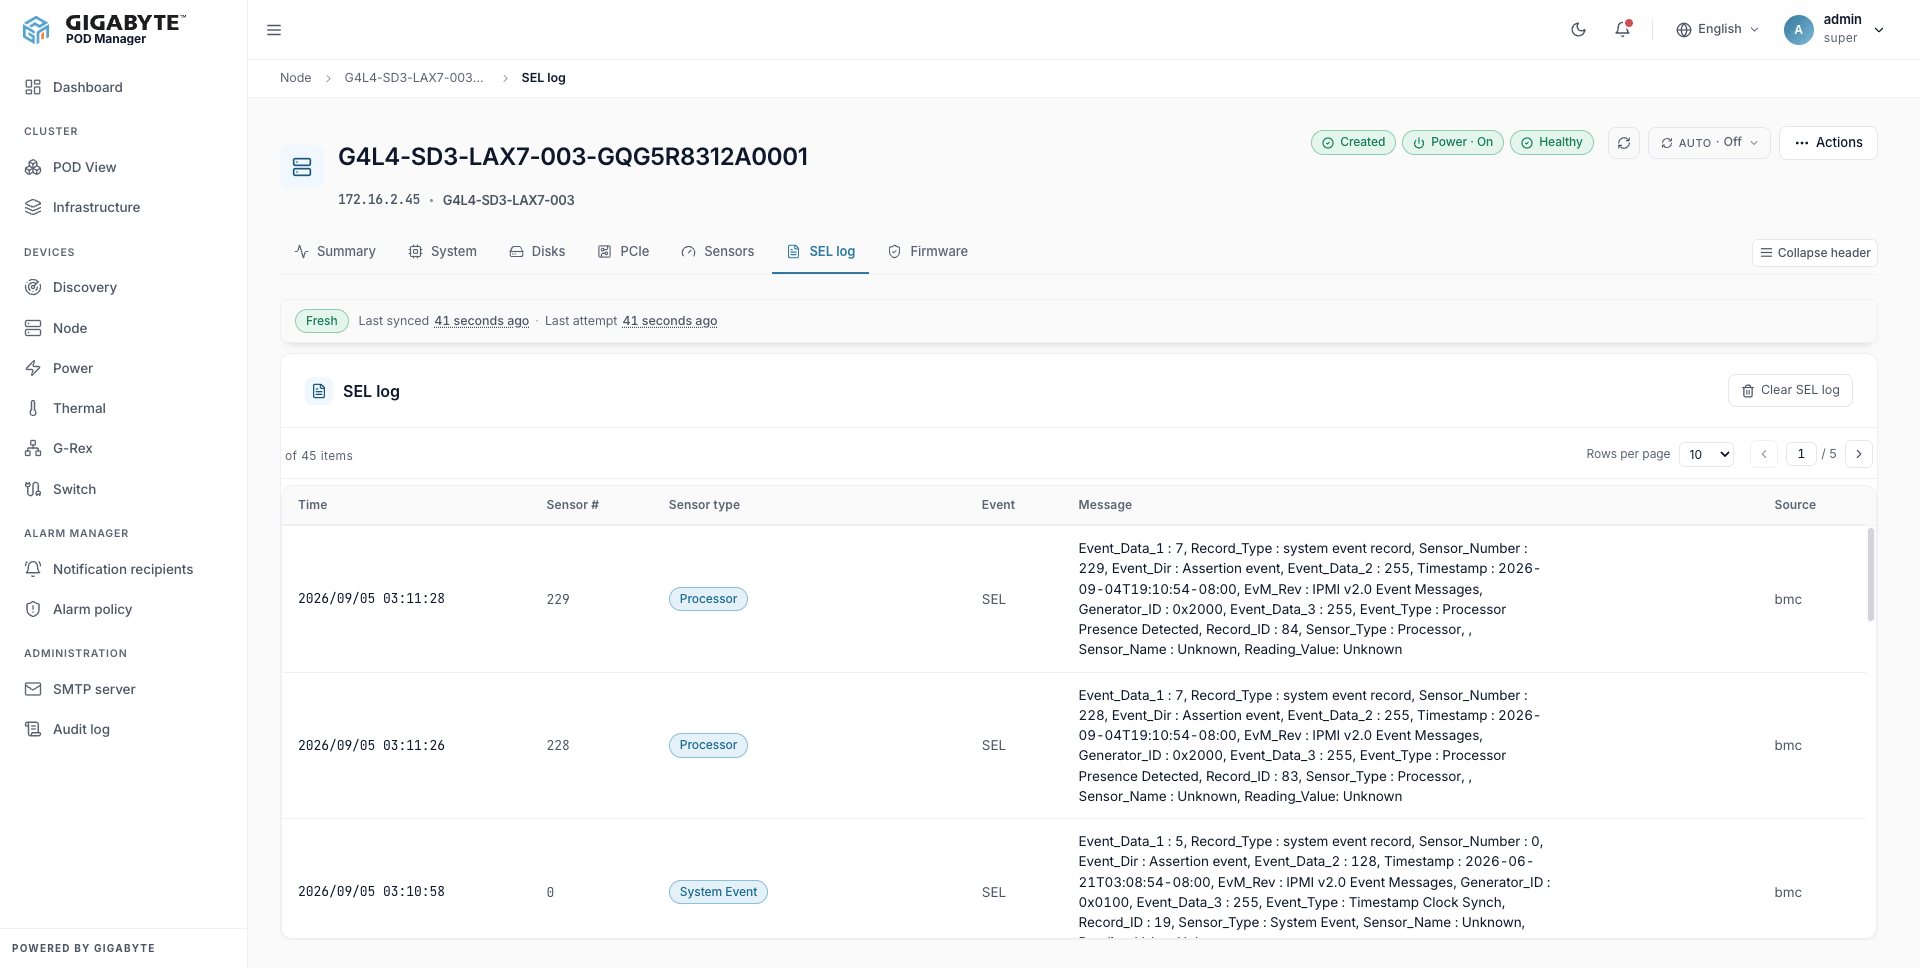
Hardware Event Diagnostics
Centrally manage BMC SEL hardware events without logging into each device individually, tracing the source and history of anomalies to speed up diagnosis.
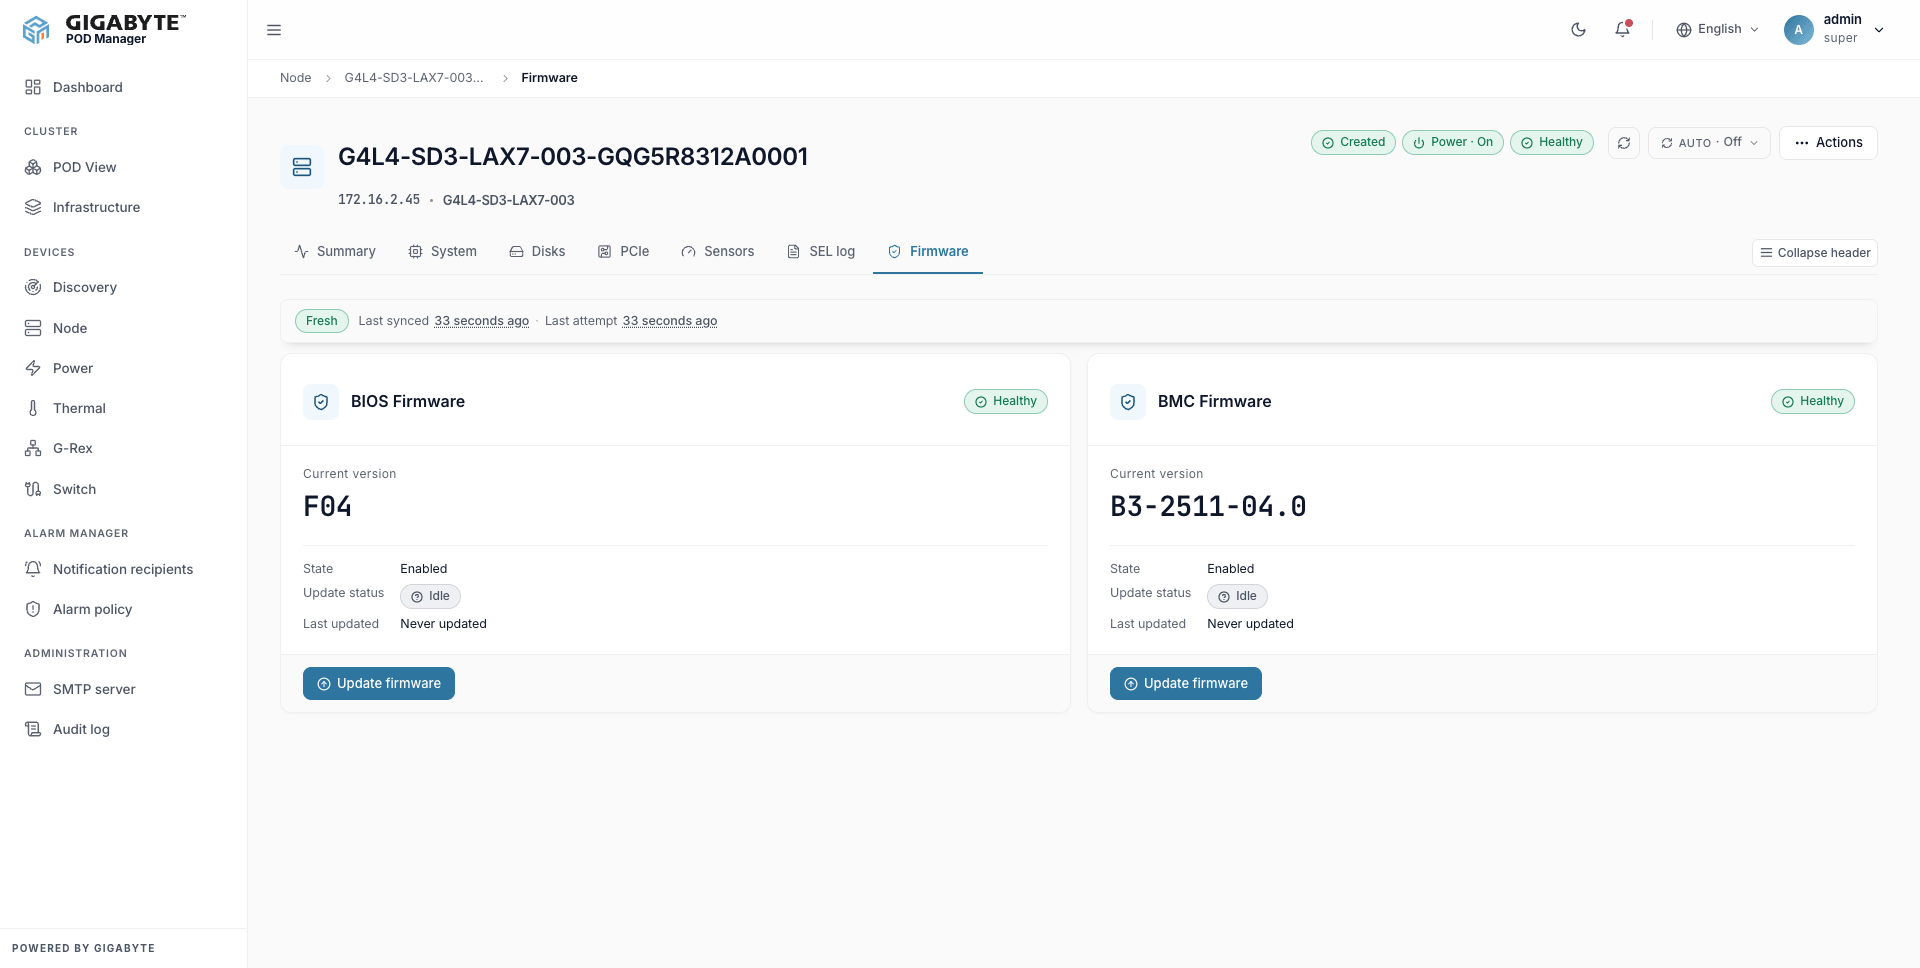
Firmware Lifecycle Management
Track BIOS and BMC firmware versions and update status from one place, simplifying firmware baselining and lifecycle management across large server fleets.
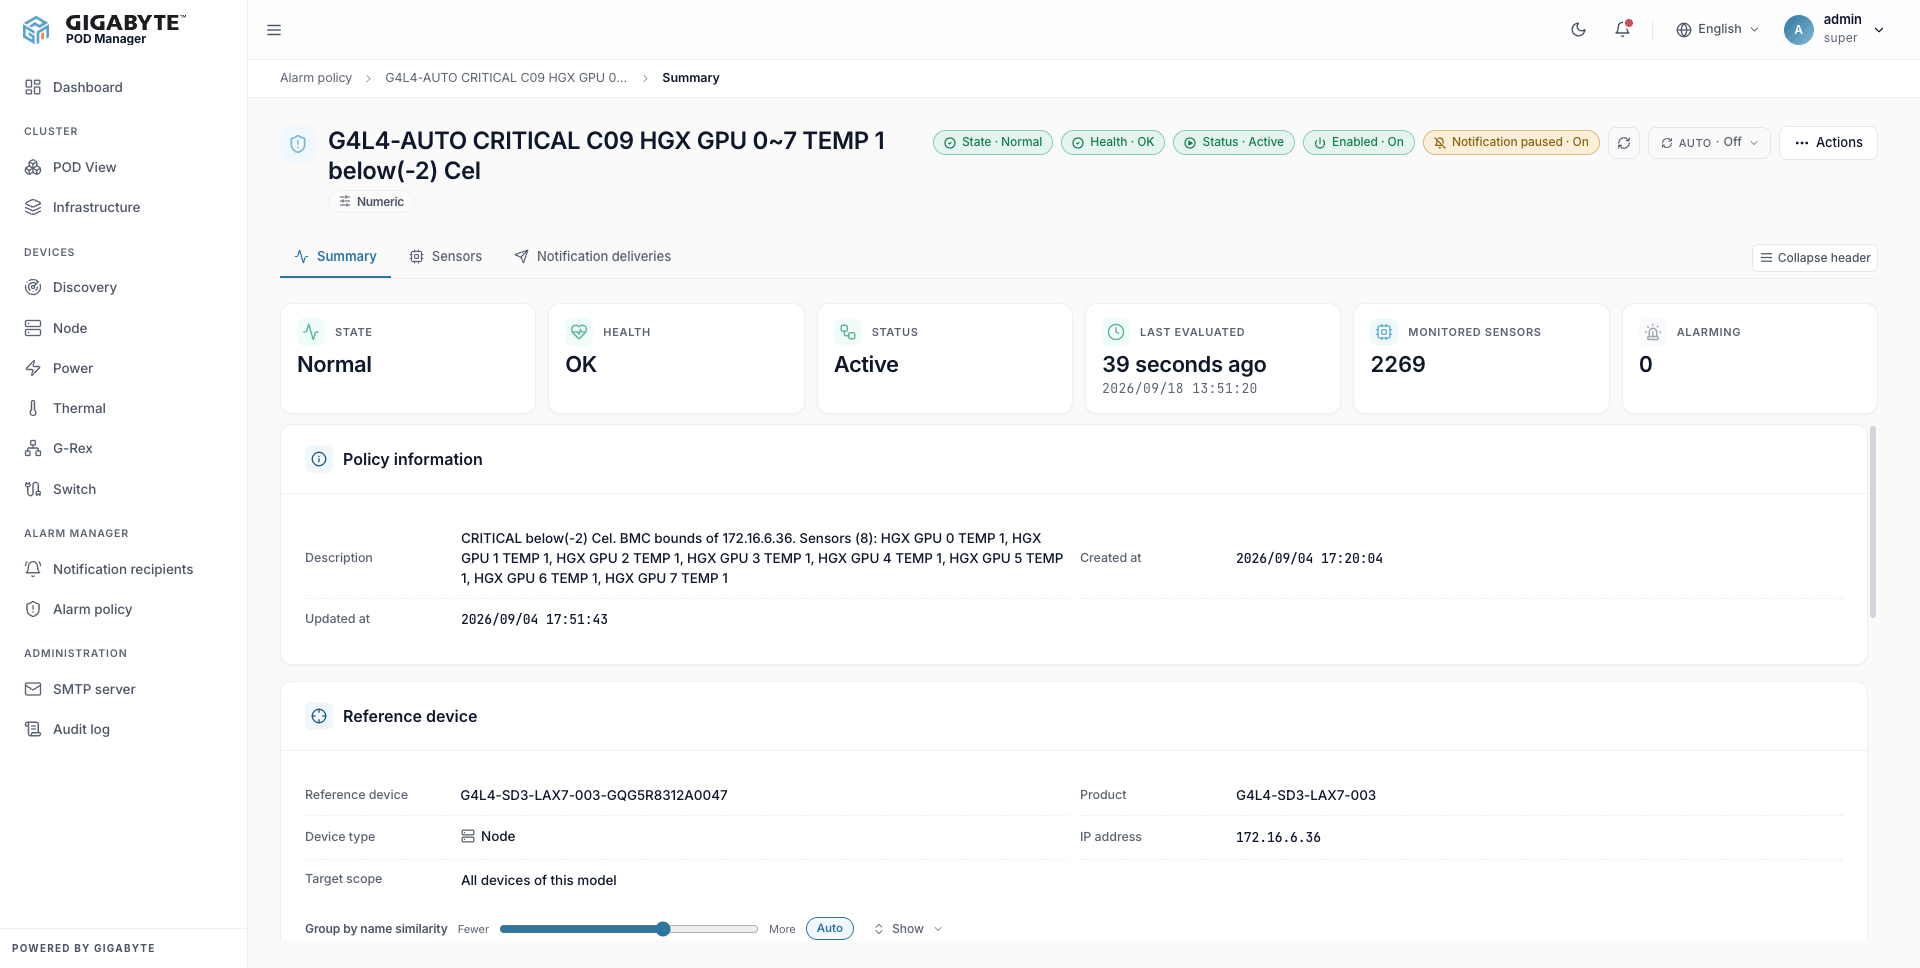
Alarm Manager
Apply consistent monitoring and alert policies across device models and sensor groups so monitoring rules stay uniform and easy to manage, even for large GPU clusters. Alarm Manager is built from two components: Alarm Policy, which sets alert thresholds per component, and Notification Recipients, which defines who is notified and through which channel (email, webhook, or chat integrations), for a complete alerting and notification workflow.
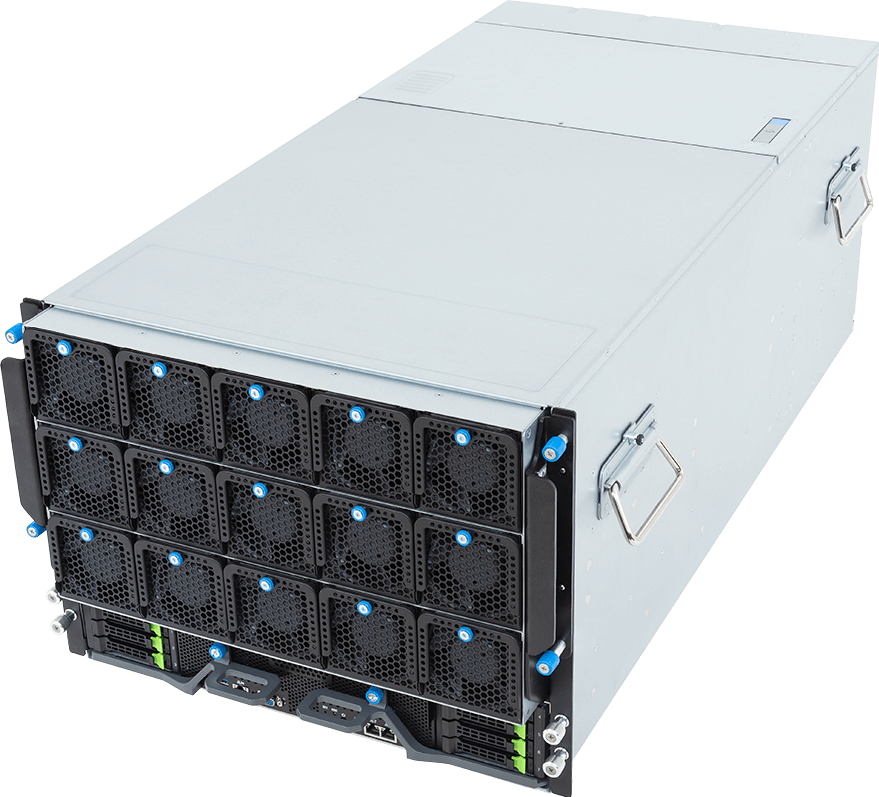
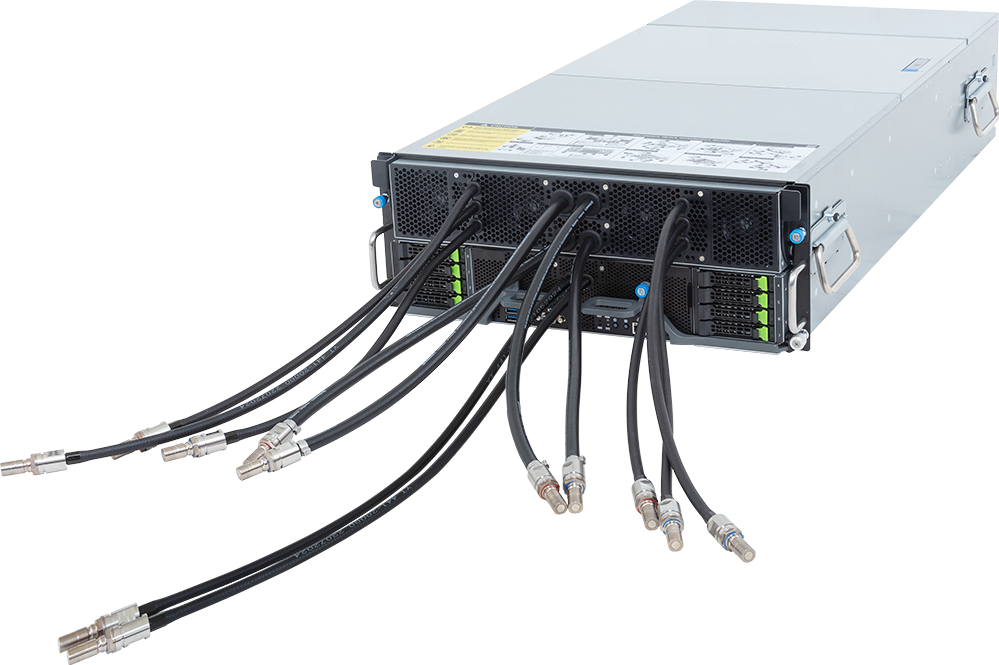
Products Optimized for POD

Resources
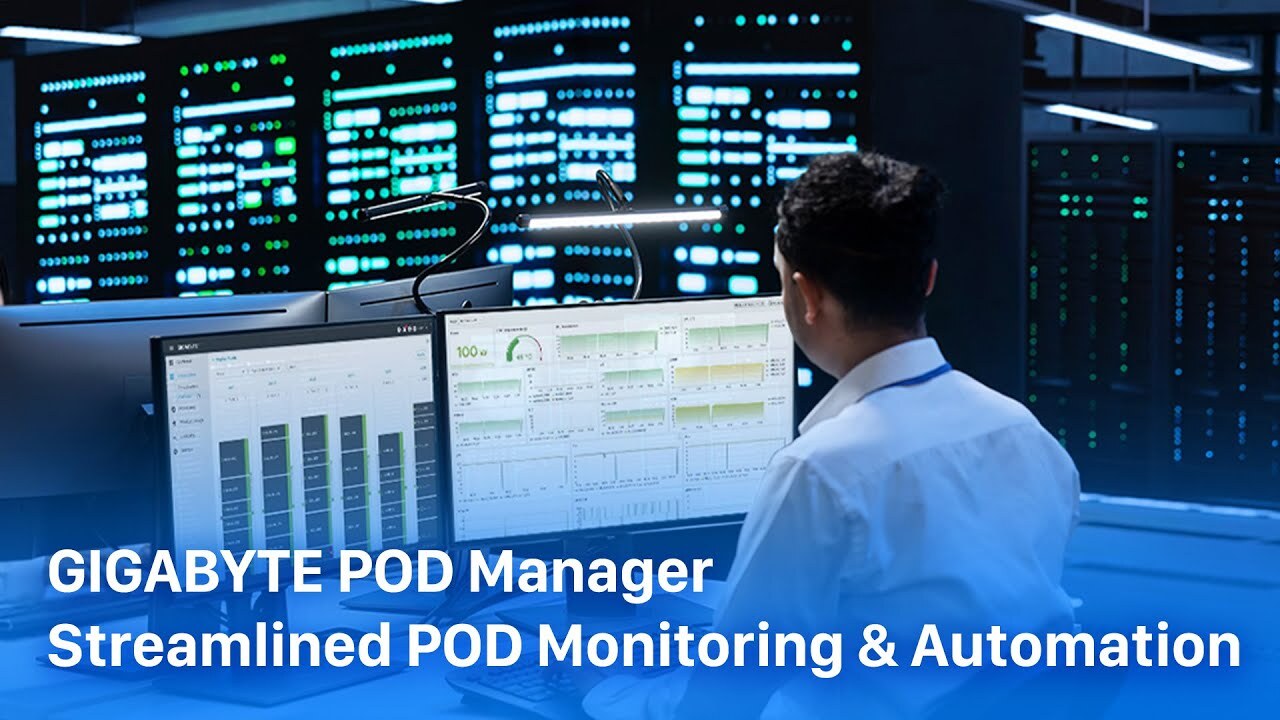
GIGABYTE POD Manager - Streamlined POD Monitoring & Automation
Watch Video
How GIGAPOD Provides a One-Stop Service, Accelerating a Comprehensive AI Revolution
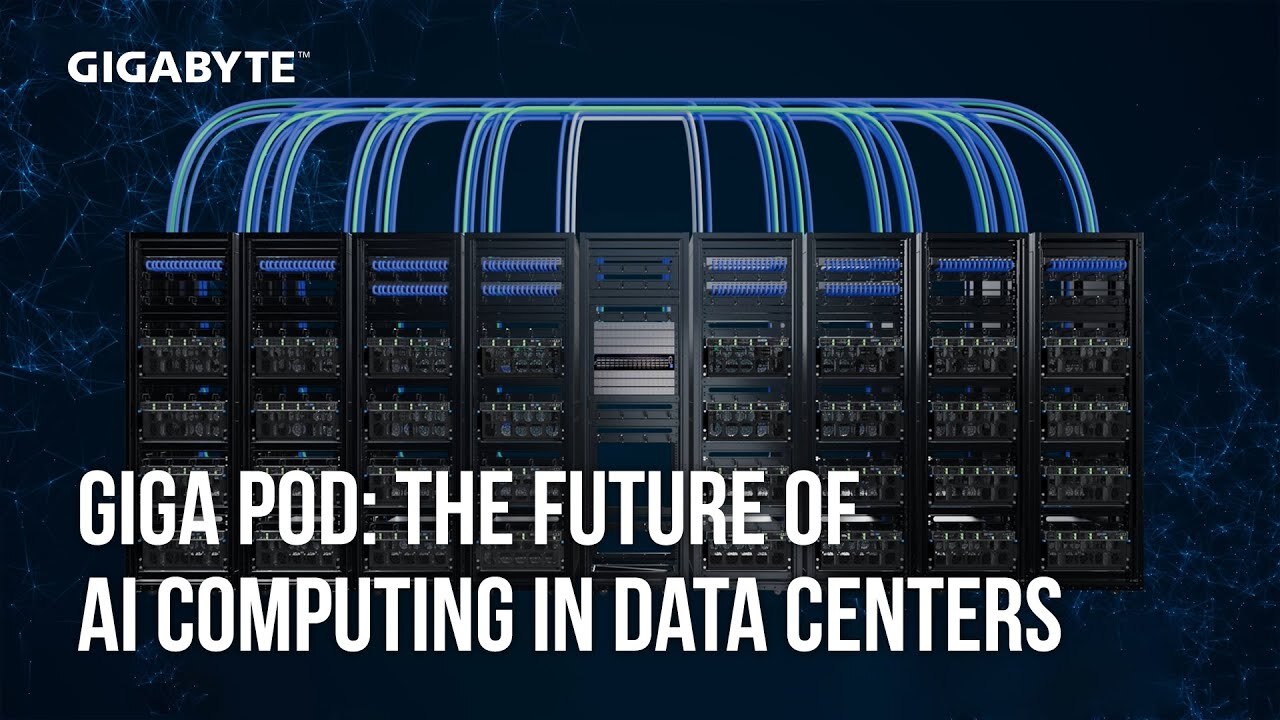
GIGAPOD: The Future of AI Computing in Data Centers
Watch Video
GIGAPOD, the Turnkey AI Supercomputing Solution
Watch Video